GlobalChatTranslator
一款 Minecraft 插件,使用 AI 实时翻译玩家聊天消息。玩家可以单独设置首选语言,消息会根据每位接收者的语言自动翻译——从而打破语言障碍,实现无缝沟通。
要求
|
|
| 服务端 |
Spigot 或 Paper 1.21+ |
| Java |
21+ |
| LLM 提供商(任选其一) |
Google AI Studio API key / OpenAI Platform API key / 自托管 Ollama 实例 |
功能
- 实时翻译 — 根据每位接收者的语言设置自动翻译聊天消息,由 Google Gemini、OpenAI ChatGPT 或自托管的 Ollama 实例提供支持。
- 按玩家设置语言 — 每个玩家通过
/gct lang 设置自己的首选语言。设置会在会话之间持久保存。
- 跳过前缀 — 在消息前添加
!(可配置)即可原样发送,不进行翻译。
安装
- 下载
GlobalChatTranslator-*.jar
- 将 jar 文件放入
plugins/ 目录
- 启动服务器一次以生成
plugins/GlobalChatTranslator/config.yml
- 编辑
config.yml 以设置你的提供商和 API key(参见 配置)
- 运行
/gct reload 或重启服务器
提供商
Google Gemini
从 Google AI Studio 获取 API key。
provider: "gemini"
gemini-api-key: "YOUR_GEMINI_API_KEY"
gemini-model: "gemini-2.5-flash-lite"
推荐模型:gemini-2.5-flash-lite, gemini-2.5-flash, gemini-2.5-pro
OpenAI ChatGPT
从 OpenAI Platform 获取 API key。
provider: "openai"
openai-api-key: "YOUR_OPENAI_API_KEY"
openai-model: "gpt-4o-mini"
推荐模型:gpt-4o-mini, gpt-4o, gpt-4.1
Ollama(自托管)
安装 Ollama 并在本地拉取模型。无需 API key。
对于实时聊天翻译,强烈建议使用较小且较快的模型(2B~4B 参数)——响应延迟比输出质量更重要。
provider: "ollama"
ollama-url: "http://localhost:11434"
ollama-model: "gemma4:e2b"
推荐模型:gemma4:e2b, gemma3:2b, qwen2.5:3b
命令
| 命令 |
权限 |
描述 |
/gct lang <code> |
gct.use |
设置你的首选语言(例如 en, ja, es) |
/gct lang |
gct.use |
显示你当前的语言 |
/gct reload |
gct.admin |
重新加载 config.yml 并应用更改 |
/gct help |
— |
显示帮助信息 |
语言代码
支持 ISO 639-1 代码。示例:ar cs da de en es fa fi fr hu id it ja ko ms nb nl pl pt ro ru sv th tr uk vi zh
权限
| 权限 |
默认值 |
描述 |
gct.use |
true |
允许玩家设置自己的语言 |
gct.admin |
op |
允许重新加载配置文件 |
配置 (plugins/GlobalChatTranslator/config.yml)
# =============================================
# GlobalChatTranslator - Configuration
# =============================================
# Translation provider to use.
# Supported values: gemini, openai, ollama
# After changing this value, run /gct reload to apply.
provider: "gemini"
# =============================================
# Gemini Settings (provider: gemini)
# =============================================
# API key obtained from Google AI Studio (https://aistudio.google.com/)
gemini-api-key: "YOUR_GEMINI_API_KEY"
# Gemini model to use for translation.
# Recommended: gemini-2.5-flash-lite (fastest, lowest cost)
# Other options: gemini-2.5-flash, gemini-2.5-pro, gemini-2.0-flash, gemini-1.5-flash
gemini-model: "gemini-2.5-flash-lite"
# =============================================
# Ollama Settings (provider: ollama)
# =============================================
# Base URL of your Ollama server.
ollama-url: "http://localhost:11434"
# Ollama model to use for translation.
# The model must be pulled in advance (e.g. ollama pull gemma4:e2b).
# For real-time chat translation, smaller and faster models (2B~4B parameters) are
# strongly recommended over large models. Response latency matters more than accuracy.
# Recommended: gemma4:e2b, gemma3:2b, qwen2.5:3b
ollama-model: "gemma4:e2b"
# =============================================
# OpenAI Settings (provider: openai)
# =============================================
# API key obtained from OpenAI Platform (https://platform.openai.com/)
openai-api-key: "YOUR_OPENAI_API_KEY"
# OpenAI model to use for translation.
# Recommended: gpt-4o-mini (low cost, sufficient quality)
# Other options: gpt-4o, gpt-4.1
openai-model: "gpt-4o-mini"
# =============================================
# General Settings
# =============================================
# Default language assigned to players who have not set a preference.
# Uses ISO 639-1 codes (e.g. en, ja, zh, es, fr).
default-language: "en"
# Format for messages that were translated.
# Placeholders: %source_lang%, %target_lang%, %player%, %message%
# Use & followed by a color code for formatting (e.g. &7 for gray, &f for white).
message-format: "&7[%source_lang% -> %target_lang%] &f%player%&7: &f%message%"
# Format for messages shown to recipients who share the same language as the sender
# (translation is skipped). Same placeholders are available.
same-language-message-format: "&f%player%&7: &f%message%"
# Show a "Translating..." action bar message to the sender while the API is processing.
# Disable this if you prefer a quieter experience or notice display conflicts.
translating-action-bar: true
# Notify players of their current language setting when they join the server.
notify-language-on-join: true
以该前缀开头的消息将原样发送,不进行翻译。
在消息投递前会移除前缀字符。
设置为 "" 可禁用此功能。
skip-prefix: "!"
每个玩家翻译消息之间的最小间隔(毫秒)。
发送速度超过此速率的玩家的消息将被拦截。
设置为 0 可禁用。
cooldown: 1000
等待 API 响应的最大时间(秒)。
如果提供方在此时间内未响应,原始消息将以未翻译状态送达,而不是被丢弃。
api-timeout: 10
将原始 API 请求和响应体记录到控制台。
有助于诊断翻译失败或意外输出问题。
在生产环境中请禁用,因为 API 密钥可能会出现在输出中。
debug: false
GlobalChatTranslator
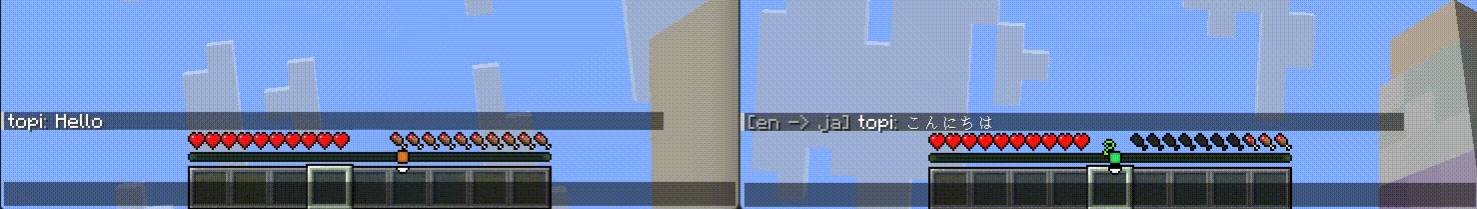
A Minecraft plugin that translates player chat messages in real-time using AI. Players can set their preferred language individually, and messages are automatically translated for each recipient — enabling seamless communication across language barriers.
Requirements
|
|
| Server |
Spigot or Paper 1.21+ |
| Java |
21+ |
| LLM provider (pick one) |
Google AI Studio API key / OpenAI Platform API key / Self-hosted Ollama instance |
Features
- Real-time translation — Chat messages are automatically translated per recipient based on their language setting, powered by Google Gemini, OpenAI ChatGPT, or a self-hosted Ollama instance.
- Per-player language— Each player sets their preferred language with
/gct lang. Settings persist across sessions.
- Skip prefix — Prefix a message with
! (configurable) to send it as-is without translation.
Installation
- Download
GlobalChatTranslator-*.jar
- Place the jar file inside the
plugins/ directory
- Start the server once to generate
plugins/GlobalChatTranslator/config.yml
- Edit
config.yml to set your provider and API key (see Configuration)
- Run
/gct reload or restart the server
Providers
Google Gemini
Obtain an API key from Google AI Studio.
provider: "gemini"
gemini-api-key: "YOUR_GEMINI_API_KEY"
gemini-model: "gemini-2.5-flash-lite"
Recommended models: gemini-2.5-flash-lite, gemini-2.5-flash, gemini-2.5-pro
OpenAI ChatGPT
Obtain an API key from the OpenAI Platform.
provider: "openai"
openai-api-key: "YOUR_OPENAI_API_KEY"
openai-model: "gpt-4o-mini"
Recommended models: gpt-4o-mini, gpt-4o, gpt-4.1
Ollama (self-hosted)
Install Ollama and pull a model locally. No API key required.
For real-time chat translation, smaller and faster models (2B~4B parameters) are strongly recommended — response latency matters more than output quality.
provider: "ollama"
ollama-url: "http://localhost:11434"
ollama-model: "gemma4:e2b"
Recommended models: gemma4:e2b, gemma3:2b, qwen2.5:3b
Commands
| Command |
Permission |
Description |
/gct lang <code> |
gct.use |
Set your preferred language (e.g. en, ja, es) |
/gct lang |
gct.use |
Show your current language |
/gct reload |
gct.admin |
Reload config.yml and apply changes |
/gct help |
— |
Show help |
Language codes
ISO 639-1 codes are supported. Examples: ar cs da de en es fa fi fr hu id it ja ko ms nb nl pl pt ro ru sv th tr uk vi zh
Permissions
| Permission |
Default |
Description |
gct.use |
true |
Allows players to set their language |
gct.admin |
op |
Allows reloading the config |
Configuration (plugins/GlobalChatTranslator/config.yml)
# =============================================
# GlobalChatTranslator - Configuration
# =============================================
# Translation provider to use.
# Supported values: gemini, openai, ollama
# After changing this value, run /gct reload to apply.
provider: "gemini"
# =============================================
# Gemini Settings (provider: gemini)
# =============================================
# API key obtained from Google AI Studio (https://aistudio.google.com/)
gemini-api-key: "YOUR_GEMINI_API_KEY"
# Gemini model to use for translation.
# Recommended: gemini-2.5-flash-lite (fastest, lowest cost)
# Other options: gemini-2.5-flash, gemini-2.5-pro, gemini-2.0-flash, gemini-1.5-flash
gemini-model: "gemini-2.5-flash-lite"
# =============================================
# Ollama Settings (provider: ollama)
# =============================================
# Base URL of your Ollama server.
ollama-url: "http://localhost:11434"
# Ollama model to use for translation.
# The model must be pulled in advance (e.g. ollama pull gemma4:e2b).
# For real-time chat translation, smaller and faster models (2B~4B parameters) are
# strongly recommended over large models. Response latency matters more than accuracy.
# Recommended: gemma4:e2b, gemma3:2b, qwen2.5:3b
ollama-model: "gemma4:e2b"
# =============================================
# OpenAI Settings (provider: openai)
# =============================================
# API key obtained from OpenAI Platform (https://platform.openai.com/)
openai-api-key: "YOUR_OPENAI_API_KEY"
# OpenAI model to use for translation.
# Recommended: gpt-4o-mini (low cost, sufficient quality)
# Other options: gpt-4o, gpt-4.1
openai-model: "gpt-4o-mini"
# =============================================
# General Settings
# =============================================
# Default language assigned to players who have not set a preference.
# Uses ISO 639-1 codes (e.g. en, ja, zh, es, fr).
default-language: "en"
# Format for messages that were translated.
# Placeholders: %source_lang%, %target_lang%, %player%, %message%
# Use & followed by a color code for formatting (e.g. &7 for gray, &f for white).
message-format: "&7[%source_lang% -> %target_lang%] &f%player%&7: &f%message%"
# Format for messages shown to recipients who share the same language as the sender
# (translation is skipped). Same placeholders are available.
same-language-message-format: "&f%player%&7: &f%message%"
# Show a "Translating..." action bar message to the sender while the API is processing.
# Disable this if you prefer a quieter experience or notice display conflicts.
translating-action-bar: true
# Notify players of their current language setting when they join the server.
notify-language-on-join: true
# Messages that begin with this prefix are sent as-is without translation.
# The prefix character is stripped before the message is delivered.
# Set to "" to disable.
skip-prefix: "!"
# Minimum interval between translated messages per player, in milliseconds.
# Players who send messages faster than this rate will have their message blocked.
# Set to 0 to disable.
cooldown: 1000
# Maximum time to wait for an API response, in seconds.
# If the provider does not respond within this time, the original message is
# delivered untranslated rather than dropped.
api-timeout: 10
# Log raw API request and response bodies to the console.
# Useful for diagnosing translation failures or unexpected output.
# Disable in production as API keys may appear in the output.
debug: false
评论 0
登录后参与评分
还没有评论,来抢沙发吧